
← All sectors / The AI transformation
081 · AI inference infrastructure & model serving
The cost per answer
Curve position
Binding constraint
Accelerator availability and the memory bandwidth that caps throughput.
Why this sector sits at Flight
We place AI inference infrastructure at Flight. The Liftoff test asks whether the repricing has happened yet, and here it plainly has. CoreWeave reported Q2 2026 revenue of $2.58 billion, more than double a year earlier, with a backlog of about $104 billion. On April 9, 2026 Meta signed a $21 billion expansion to scale its inference workloads. A generalist investor already knows this story.
The binding constraint is no longer demand. It is the cost of financing the build-out: CoreWeave's Q2 net interest expense was $640 million, against an operating loss of $49 million.
We would move this sector to Orbit once revenue growth among the listed providers settles to a steady rate and backlog stops compounding.
Reviewed on a two month cycle. The position moves only when a dated, verifiable change in the binding constraint justifies it.
Heatmap / How this sector's stocks are moving
| Stock | Price | 1 Day | 1 Week | 1 Month | Year to date |
|---|---|---|---|---|---|
| $NVDA | $200.13 | −3.17% | −7.08% | −16.35% | +7.31% |
| $CRWV | $48.42 | −9.90% | −24.26% | −47.21% | −32.38% |
| $NBIS | $141.52 | −6.67% | −22.39% | −43.36% | +69.07% |
| $NET | $266.58 | −2.57% | −16.36% | −24.91% | +35.22% |
| $AMD | $488.78 | +1.01% | −15.50% | −24.74% | +128.23% |
| Sector average | −4.26% | −17.12% | −31.31% | +41.49% |
Prices as of November 5, 2026. The sector's move is the equal-weighted average of these listed companies, a market proxy for context, not recommendations. See it on the full heatmap →
Sentiment / The mood in this sector's stocks
Since 2018, AI inference infrastructure & model serving has been in Capitulation and steady 11 separate times. After those, its stocks beat their usual three months 5 times (45%), by a median of −12.1 points.
Confidence: low, a split like this is common by chance, so no edge is called.
Training a model is a one time capital event. Serving it happens millions of times a day forever, and at scale the cost per answer determines whether an AI product has a viable margin. Optimizing inference is now its own industry.
Historically the entire conversation was about training scale, because that is where the headlines and the largest clusters were. As deployment matured, the economics shifted to serving, which is where most compute now goes.
The structural driver is unit economics. An application paying more per query than it earns cannot scale, so every serious deployment eventually invests in quantization, caching, batching, routing, and cheaper silicon.
The technology layer spans inference optimized accelerators, serving frameworks that batch and schedule requests, quantization and distillation to shrink models, key value caching, speculative decoding, and the routing layers that send easy queries to cheap models.
Adoption economics are directly measurable in cost per thousand tokens or per request, which makes procurement unusually rational and vendor comparisons unusually brutal.
The beneficiaries include inference chip designers, the neocloud providers renting capacity by the hour, serving software vendors, and the memory manufacturers whose bandwidth caps throughput.
The value chain runs from silicon through cloud capacity and serving software to the application. Memory bandwidth is the physical constraint that determines how much of the chip can actually be used.
The overlooked layer includes memory and interconnect suppliers, inference optimization software vendors, smaller cloud providers specializing in inference rather than training, and the power and cooling suppliers behind them.
Competitive dynamics pit the dominant accelerator ecosystem against challengers competing specifically on inference cost per watt, where the software moat is weaker than in training.
Risks: the segment is fully levered to AI application demand, price competition among providers is intense, model efficiency gains reduce compute per query, and capacity gluts are possible if demand growth slows.
What to watch: cost per token trends at major providers, inference specific silicon launches, memory bandwidth in new accelerators, and neocloud capacity utilization.
Coverage / Daily Disruptor issues in this sector
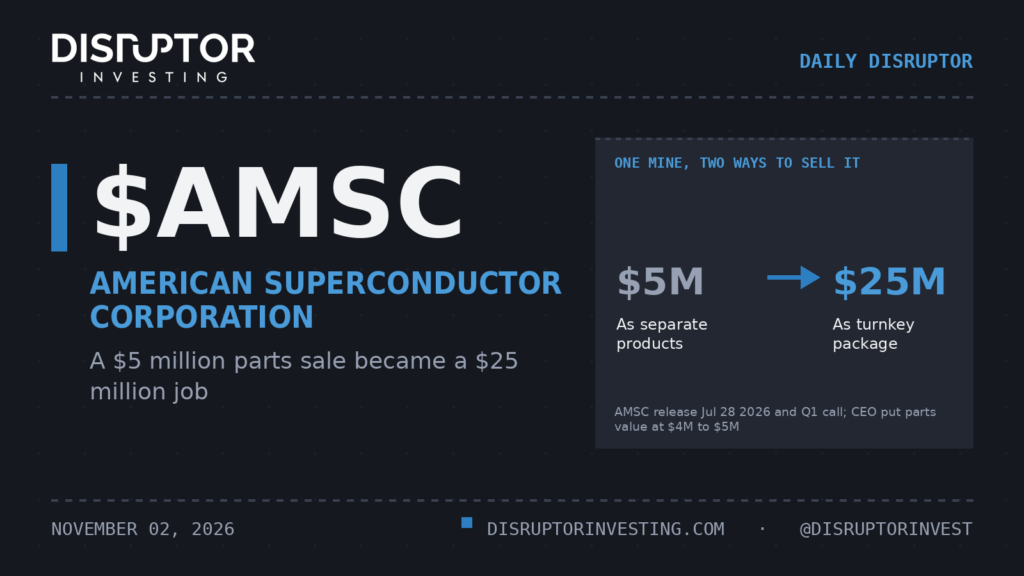
November 2, 2026
Daily Disruptor: $AMSC, the $25 million mine hookup behind a margin scare
AMSC now sells utilities the whole grid connection for new mines and fabs, and Wednesday's results show whether its record order book turns into revenue at…
Read the issue →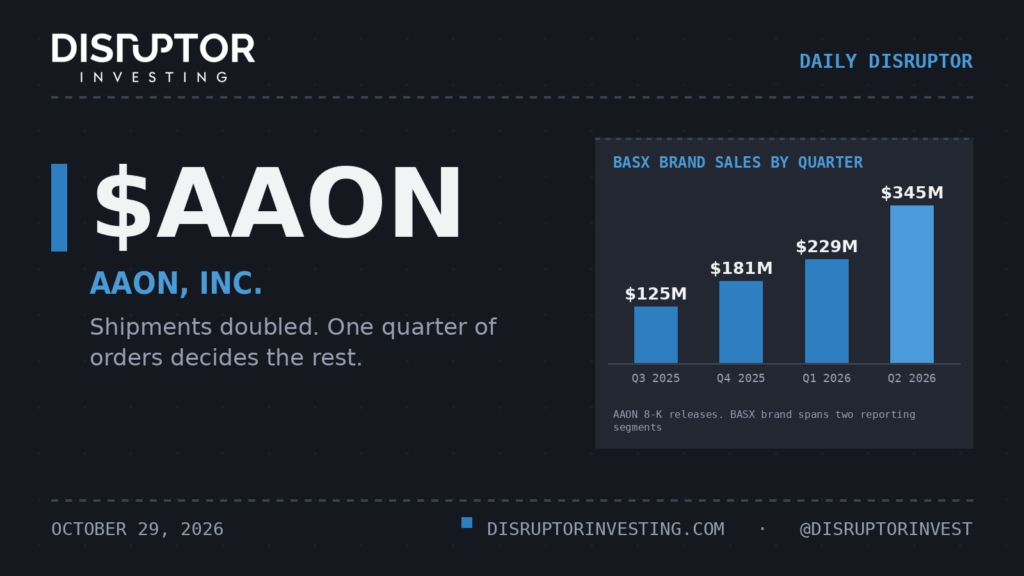
October 29, 2026
Daily Disruptor: $AAON, the factory caught up, now the orders have to
AAON's BASX data centre cooling business has broken its factory limit, but a thin June order book means November's report is the real test.
Read the issue →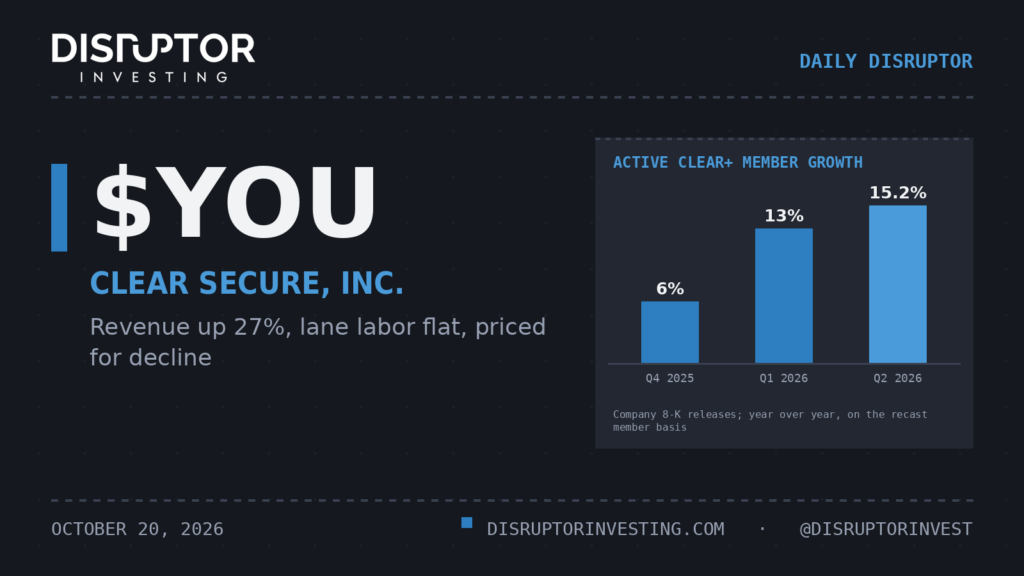
October 20, 2026
Daily Disruptor: $YOU, revenue up 27% while lane labor stayed flat
CLEAR's eGates are letting airport revenue grow on flat staffing costs, and the share price still assumes free cash flow shrinks, two weeks before the Q3…
Read the issue →